What Jev is, and what I learned building an entire city with it
Published on
Last week, out of nowhere, the company TypeSafe AI (founded by a former OpenAI employee who worked on the InstructGPT papers and others) came out of stealth and made quite a lot of noise with the launch of Jev. With all the hype, the crowd’s reaction, as usual, split fast between the “it’s 100x faster, 100x cheaper, doesn’t hallucinate” folks and the “it’s just a BERT with 2026 marketing” folks. Both sides have a piece of the truth, and neither one tells you whether it’s worth using.
If you haven’t seen what it is yet, the official demo is a bot playing Doom at 10 queries per second, reading the game state as structured text and not as an image, for about 7 dollars an hour. Reeeeally cool and impressive:
To understand better what Jev is (and isn’t), I spent my Sunday building a little project: a simulated city with 50 people who live 24 hours a day, form couples, cheat, gossip, get sick and die. It ran for 14 hours straight, 74 simulated days, almost 11 thousand requests, and cost $1.05 counting both models I used.
But what is Jev, anyway?
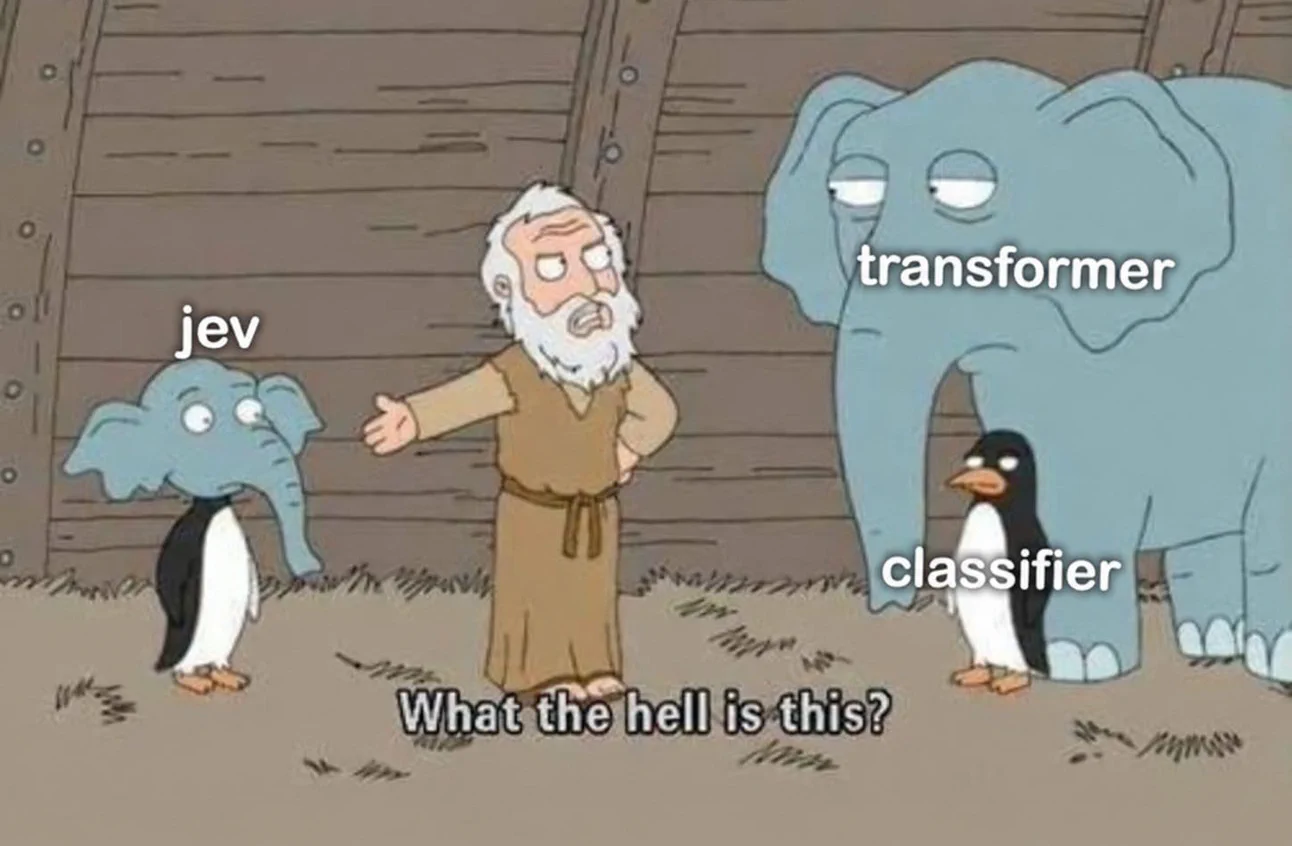
The whole discussion is about which of these three boxes Jev fits in, and the honest answer is that it doesn’t quite fit in any of them. That’s what I try to explore in the article below.
What it is (and what it isn’t)
Jev is not an LLM like GPT, Claude or Gemini. It doesn’t generate any text at all.
You send two things: a state (any JSON, whatever your application knows) and a set of typed questions. It answers all of them at once, in a single parallel pass, and returns typed values with a probability distribution.
There’s no parsing and no “please answer in JSON”, and it has no way of returning an option you didn’t offer. Jev produces all the answers at the same time, because they don’t depend on each other.
TypeSafe calls this a “System One model”, a reference to Kahneman’s fast, automatic thinking. I’ll go ahead and say it: yes, the name is marketing-speak.
One interesting thing is the cost: the model isn’t open, but via API they charge $0.042 per 1 million input tokens and ZERO for output (they say it’s so cheap it’s not even worth charging for). It’s SUPER cheap.
How you use it
There are only three possible kinds of question (and combinations of them):
Choicepicks one label from a map that you define:
from typesafe_sdk import Choice, TypeSafeClient

client = TypeSafeClient()
r = client.system_one(
    state={"ticket": "I was charged twice on order A-104"},
    questions={
        "team": Choice(
            instructions="Which team should handle this?",
            criteria={
                "billing":   "payment or subscription problems",
                "technical": "bugs or integration problems",
                "sales":     "pricing or account questions",
            },
        ),
    },
)

r.answers["team"].choice         # "billing"
r.answers["team"].confidence     # 0.85
r.answers["team"].probabilities  # {"billing": 0.90, "technical": 0.07, ...}
Scoreplaces the answer on an ordered scale, and the result comes back between the levels:
Score(
    instructions="Based on the text, how angry does the customer seem?",
    criteria=["calm", "annoyed", "angry", "furious"],
)

# .score -> 2.4
Noulis a statement, and it returns the probability of it being true:
Noul(
    instructions="The customer is explicitly asking for a refund",
    criteria={"true": "asks for the money back",
              "false": "complains but does not ask"},
)

# .noul -> 0.97
To use it, they offer a raw HTTP API or their own SDK (typesafe-sdk), and under the hood they’re pydantic models. Those Choice, Score and Noul classes I showed above get instantiated at call time, and the validation happens at construction. If you pass a key that doesn’t exist, it blows up right there, not on the server.
The criteria are defined per request. There’s no setup step and no training.
In my city project, one of the questions is “who is this person going to talk to?”, and the options are exactly who is in that room at that second. Every call is a different list. Another question removes the “gossip” option for anyone who doesn’t know any rumors yet.
The city project
For this little project, I wanted something more creative, instead of just building a ticket classifier. I remembered the Stanford generative agents paper, which ran 25 agents in a simulated town for several days.
The problem there is that, running each decision as an LLM completion, it ended up slow and expensive. If Jev is what it says it is, that latency and cost should practically vanish. Is it?
With Claudinho’s help (that’s what I call Claude), I built a city with 18 places (tavern, chapel, pier, square, market) and 50 people. Each one with an age, a trade, two personality traits, a life goal, memory, a trust graph with the others, and sometimes a secret (like an affair she was having or something bad she did in town).
For every second of real time, the city clock advances two minutes. People work, walk around, age, get sick, die. Strangers arrive. And when people gather in a place, Jev decides what happens. Here’s a video of the final project:
But to run well, there are a few details. The naive way would be one request per agent, which would give you fifty people and fifty requests per round (ouch). But since the state (what time it is, where the agents are, who’s present, what just happened there) is already shared by everybody in that room, you can just send everyone’s questions together in one go.
So, if there are 8 people in a tavern, that becomes one request to Jev, with 64 questions. Fifty people spread across 18 places turn into about 12 scenes per round, not 50 requests. This only works because the pass is truly parallel. Here’s what I measured:
| people in the room | questions in the request | p50 latency |
|---|---|---|
| 2 | 16 | 328 ms |
| 4 | 32 | 337 ms |
| 6 | 48 | 334 ms |
| 8 | 64 | 339 ms |
What’s great is that latency doesn’t change with the number of questions, so it’s worth grouping as many people as possible into a scene. I stopped at 8 people because the documentation warns that accuracy drops when the state bloats.
That way, in an interaction, what can happen is that Jev answers “Iris talks to John, about a rumor, and leaves feeling 0.31 attracted”, and after that it’s deterministic Python code (to apply the new trust value between those people, the rumor spreading to whoever was in the room, the attraction accumulating, and if it crosses a threshold with reciprocity, a couple is born).
The account limit is 1,200 requests per minute (that is, 20 per second), and I thought that could be a bottleneck, but far from it. With the grouping by room and the cap I set of 2 dollars a day, I use 0.21 requests per second, almost a hundred times below the limit.
The final simulation numbers
I ran the city simulation for ~14 hours of server uptime, which gave 74 simulated city days.
| requests | tokens | spend | |
|---|---|---|---|
| Jev (decision) | 10,991 | 22.7 M | $0.956 |
| LLM (narration) | 1,743 lines | $0.090 | |
| total | $1.05 |
That “LLM (narration)” was just a GPT-4.1-nano without thinking that I left running to better translate each action and consequence into text. That would come to $1.72 a day if you left it running. The p50 latency stayed between 289 and 363 ms over the 12 hours I monitored, with a median of 315 ms.
Since Jev only charges for input and output is free, the 22.7 million tokens are all things I sent to it. And within what I send, what weighs the most is the criteria rather than the states. For example, in an 8-person request, the state is 689 tokens (17%) and the questions are 3,321 (83%), because the option descriptions repeat once per person.
Where Jev’s probability comes from
What TypeSafe says is that Jev is trained with RLCD, short for “Reinforcement Learning for Calibrated Decisions”. While RLHF trains the model to give answers that human raters approve of, RLCD would train it so that the probability matches the real hit rate. In other words: among all the answers it gives with 90% probability, about 90% should be right.
That’s different from an LLM and different from a regular classifier. An LLM gives you token logprobs, and you can extract something like confidence from them. TypeSafe argues that, even when you ask for a confidence estimate, LLMs tend to be overconfident and inconsistent. A trained classifier, on the other hand, usually has reasonable probabilities for the classes it was trained on, and you can calibrate it with temperature scaling on top of a validation set. What it doesn’t do is give you calibrated probability for classes you just made up.
In practice, that’s what lets you use confidence as a business rule. In my project, a fight only happens above 0.45 confidence, otherwise it becomes just bad vibes. It only makes sense if the number means something.
However, TypeSafe described what RLCD is supposed to do without actually opening the model or publishing enough for someone to evaluate the algorithm. You have to trust it, or measure it yourself on your own examples.
In my city I can’t measure this, because to calibrate you need to compare the probability with the hit rate, and for that you need to know what the right answer was. There’s no right answer in my case for whether Iris should have talked to John or not.
Whoever actually measured it was the decision-model-benchmark, which put Jev up against eight LLMs and three baselines, with an answer key and the raw data published. In its calibration table, Jev shows up as the worst of the models in two batteries.
I downloaded the raw data and recalculated everything with their own ECE function. I reproduced the published table exactly, which means the math is right, and the story splits in two.
In the spam battery, which is binary, the bad number comes from reading the wrong field. The benchmark’s adapter uses confidence as if it were the probability of being right, but it isn’t: it’s the probability of the chosen option rescaled so that a random guess gives 0 and certainty gives 1 (in the example way back at the start, 0.90 becomes 0.85), and with two options that difference weighs a lot. Recalculating with the probability of the chosen option, Jev’s ECE drops from 0.249 to 0.090, and it goes from last to third best among the nine models, ahead of Claude Haiku and Claude Sonnet. In the 77-option batteries the swap barely changes anything, because with many options the two numbers almost coincide.
In the battery that tests whether the model admits it doesn’t know, the bad number is real, and the right field makes it worse. The items in that battery are built to have no answer: either the correct option isn’t even on the list, or nothing in the text allows a decision. The honest behavior is low confidence. Using the probability, Jev’s ECE goes from 0.246 to 0.347. When none of the options was right, it put 90% or more on a wrong option in 59 of 300 cases. The LLMs in the same study admitted they didn’t know between 65% and 100% of the time. Jev, between 35% and 50%, depending on which field you read.
Putting the two things together: on questions that have an answer, Jev’s probability is reasonably calibrated. When there’s no information at all, it doesn’t notice, picks an option, and sometimes picks it with conviction. For the kind of use I defend in this post, that matters, and I come back to this point in the conclusion.
And the architecture? Does it use embeddings?
Short answer: nobody on the outside knows. What’s published is that it isn’t autoregressive, that it evaluates the questions independently and in parallel (one answer doesn’t become context for another), and that the training is RLCD, that’s it. There’s no paper, no architecture details, it doesn’t say whether it’s an encoder or a decoder, it doesn’t say how the answers are read out of the model.
There’s a project trying to reconstruct the idea on top of a 0.8B Qwen3.5, with a “prefix-fork” architecture that evaluates several questions against a shared state in one pass. But the authors themselves are explicit that it’s reverse engineering from a hypothesis, because “TypeSafe has not published Jev’s architecture”.
The best-grounded guess I’ve seen is from Sebastian Raschka, PhD, and he made a point of saying it’s only a guess. His bet is a small encoder-style model, like ModernBERT, trained with something similar to RLCR, a method from the paper Beyond Binary Rewards that adds to the correctness reward a term that punishes badly calibrated confidence. It comes from someone who’s been training this kind of model for years, it’s plausible, but it’s still “just” a hypothesis.
There’s another very similar one that they say did Jev before Jev, and lost the marketing fight. Laya, from ConvAI Innovations, is a 421M ModernBERT with the same three kinds of question as Jev, open weights under Apache 2.0, running locally. It’s the most complete open reimplementation I found, and it shows you can build something with Jev’s format on top of an encoder (but of course, it doesn’t show that Jev is that).
Does it work for my case? It depends…
Grading rubrics in RL training
I think so, and it’s probably one of the best fits that exist for it, with one caveat. The format matches, that is, you have a criterion, you want a score or a boolean, you need it in huge volume and cheap, and you want the probability to weight things instead of just the label. The caveat is that the rubric item needs to be atomic. Jev reads things to the letter, and the model’s own weak spots page warns that negations and implicit conditions are read literally and that multi-step reasoning costs accuracy. “This answer is correct and well written” is going to go badly. “This answer contains the requested formula” goes well.
For comparison: an LLM as a judge handles more complex rubrics, but costs sooo much more. A trained classifier is cheaper still, but you need labeled data per rubric, and rubrics change all the time.
If I were putting together an RLVR pipeline today, I’d test Jev on the verifiable, objective items, and leave the LLM for the ones that require compound judgment.
Running in a pipeline together with an SLM
The question I saw a lot of people asking was: “use Jev or an SLM?”. TypeSafe’s own documentation proposes using “Jev + SLM”, and I think it can make sense in some cases:
- Extract with a small, cheap model
- Verify with Jev, with specific questions for each field, and return the probability of each one being wrong
- Escalate to a more powerful (and more expensive) model only the fields where the verification flags something
The result they publish on 100 prompts is keeping almost all of the top model’s quality, but at a much lower cost (computational and financial).
They gave a web scraping use case, finding on an NYU page the date registration opens for the 2024-2025 fall semester, returning two fields, the date and a description. The catch is that the page doesn’t have that information.
The small model (gpt-5.4-mini) returns this:
{
    "registration_open_date": "",
    "description": "Registration opens for the fall semester"
}
The date came back empty, which is correct. But the description is made up, and it looks like it copied the example text that was in that field’s documentation in the schema. The output is valid in type, but false, which is the “doesn’t hallucinate” problem I discuss further down.
Then Jev comes in, with a battery of Noul per field, where true means “something is wrong here”:
hallucinated: is the extracted value unsupported by the source text?off_target: does the source not actually report the thing the field describes, and the value was pulled from incidental text?absence_wrong: did the field come back empty, and does the source contain something that makes that emptiness wrong?
And the answers:
description::hallucinated                 0.95      # fires
description::off_target                   0.85      # fires
description::unreasonable                 0.58
registration_open_date::absence_wrong     0.14
They set it so that any metric above 0.7 fires. Two passed, so the extraction goes to a more powerful model, like gpt-5.5 with high effort, which returns both fields empty, which is the correct answer. Notice that it didn’t just say “this is wrong”: it gave 0.95 for the hallucination and 0.14 for the empty field, that is, it separated which of the two fields was the problem.
By their math, the reasoning model comes out to about $0.10 per extraction and the small one about $0.001. Jev charges $0.042 per 1 million input tokens, so you’d have to send 2.4 million verification tokens to spend what a single call to the expensive model costs.
Reading this, Jev stops being a competitor of the SLM and becomes a piece in a pipeline that makes the SLM more useful for many use cases.
They also give the example of using it as a guardrail in a pipeline, that is, putting Jev as a triage layer on the input and output of an LLM, with all the risk questions in a single request, instead of a second LLM watching the first.
If I had to point to Jev’s strongest fit today, it would be this one. Not replacing any model, but being the cheap judge between models.
Robotics
I can’t say, because it’s not exactly my area, but I believe that since it doesn’t run locally, it loses the big advantage. Still, besides the Doom example, other really fun things showed up on social media, like Jev playing Minecraft and using Tesla’s self-driving system:
The criticisms
I agree with several of them, at least in part.
“Jev is just a classifier”
This is the most repeated criticism, and it’s right about the mechanism: every answer is a selection from a list. If your classes are fixed and you have labeled data, you could, yes, just use a classifier like DeBERTa, because it’ll come out cheaper and you keep the weights.
The catch, which is something Sebastian Raschka also mentioned in his post, is that a regular encoder classifier is a single-purpose, specific model. You generally train one for spam analysis, another for sentiment, another for ticket routing, etc.
Jev, on the other hand, is much more of a generalist. The same call classifies email, plays Doom and, in my case, decides what a person does in a tavern. In the simulated city, the options for who to talk to change on every call, and there was no training set for that, it worked from scratch.
Raschka’s bet is that the secret lies more in the data than in the training algorithm, with good API design on top. He compares it to the 2022 ChatGPT, which was an improved version of InstructGPT, where what made the difference was the data.
“A 200M-parameter SLM would do what Jev does”
This is another criticism I saw a lot.
My friend Luciano Martins from Google DeepMind (who’s on the team of those who think Jev is a classifier with marketing) tested a version of this criticism, and his experiment is worth telling in full.
He took Gemma-3-1b, a 1-billion-parameter model, and did with it what Jev does: he built the prompt with the context, the question and the options, ran a single pass, looked only at the logits of the allowed words and applied softmax to them. That way the model has no way of answering outside the list. He ran it on 50 classification questions of eight types (churn, sentiment, support department, priority, spam, moderation, topic and logical inference) and it got 43 right.
His point is right, and it’s the most important one in the experiment: the typed-output guarantee isn’t magic. A small model with about fifteen lines of code delivers the same guarantee of never answering outside the schema.
I ran the same 50 questions on Jev, with the same answer keys. It got all 50 right, including when it received only the option words, with no description, which is exactly what Gemma received. With the 50 questions in a single request, it also got all of them right, using 65% fewer tokens than sending them one at a time. The whole test cost less than a cent.
Gemma’s seven mistakes were in two tasks. Two were in department, two tickets about the account that it sent one to the technical team and the other to sales. Five were in priority, all off by exactly one level (and it never answered Low, not even for a typo in the website footer).
Comparing raw logits of different words favors the more common words, a bias described in the paper Calibrate Before Use, which also proposes a cheap fix called contextual calibration. I reproduced Luciano’s method, with my predictions matching his on the 50 questions, and applied the fix. The priority task went from 1 to 4 right out of 6, which confirms the diagnosis. But the same fix cost one right answer in sentiment and another in moderation, and the total went from 43 to just 44. Giving it descriptions of the options, which is what Jev’s API asks for, made Gemma worse.
| correct out of 50 | |
|---|---|
| Gemma-3-1b, original method | 43 |
| Gemma + contextual calibration | 44 |
| Gemma + option descriptions | 39 |
| Gemma + both | 42 |
| Jev, labels only | 50 |
In other words, the accuracy gap survives the known fixes. But the bigger difference is in the number the notebook calculates and then throws away: the probability.
Gemma’s barely carries any information. Across the 50 questions, it gave on average 0.96 probability to the chosen answer, while being right 86% of the time, and when it was wrong it still gave 0.90. To look at this up close, I wrote 14 new sentences, 8 designed to have no possible decision and 6 designed to be obvious, and sent them to both without saying which was which. Comparing the probability of the chosen option in the two models, Jev gave 1.00 on the obvious ones and 0.82 on average on the ambiguous ones. Gemma gave 1.00 and 0.93, and after contextual calibration the difference between the two groups practically disappeared.
Two examples sum it up well. For the sentence “It works, I suppose.”, Gemma answered Positive with 1.00. Jev answered Negative with 0.59 and Neutral with 0.40, which is honestly what that sentence is. And for the sentence “All production databases are unreachable and every customer is offline.”, which was one of the obvious ones, Gemma answered “High” with 1.00. The right answer is Critical, and it got it wrong without any sign of doubt.
That matches the independent benchmark from up above: Jev’s probability tracks how ambiguous the question is. What it doesn’t detect is a total lack of information.
The limits of this test also need to be stated. It’s 50 synthetic questions, several too easy, and Jev hit the 100% ceiling, so the test doesn’t measure how much better it is. It’s a 1B model against one of undisclosed size. Latency is also hard to compare, because Jev sits around 300 ms (but via API from Brazil), and the 1B Gemma depends on whatever GPU you have running locally. And Gemma still has something Jev doesn’t: it runs locally, without depending on the network, with zero marginal cost once you have the GPU.
“Jev doesn’t hallucinate”
It’s not quite like that. It’s true that Jev can’t return a value outside the schema. But it can be completely wrong inside the schema, and it was in several cases I tested, some of which I already showed above.
So, fans, calm down.
Conclusion
Jev is a piece with a specific output format that solves a specific problem well: typed decision, with probability, over a state you assemble at runtime, cheap enough to run in a loop. The probability holds up when the question has an answer and fails when it doesn’t, because it doesn’t notice the absence of information.
If that’s your problem, it’s very good at it, even in this more generalist setting. But if your classes are fixed and you have data, train a classifier. If you need the model to write something, use an SLM or an LLM.
And the question “Jev or a small model?” is probably badly formulated. The strongest use I’ve seen for it isn’t replacing any model, it’s working inside a pipeline with a smaller, cheaper model, verifying what a small model extracted or deciding what a small model will write afterward, like in my city.
The code is open at github.com/fabriciocarraro/smallville-247, with the measurement scripts that produced the city’s numbers.