Revolut cuts AI costs by 90% by swapping Claude for a local Chinese model
Published on
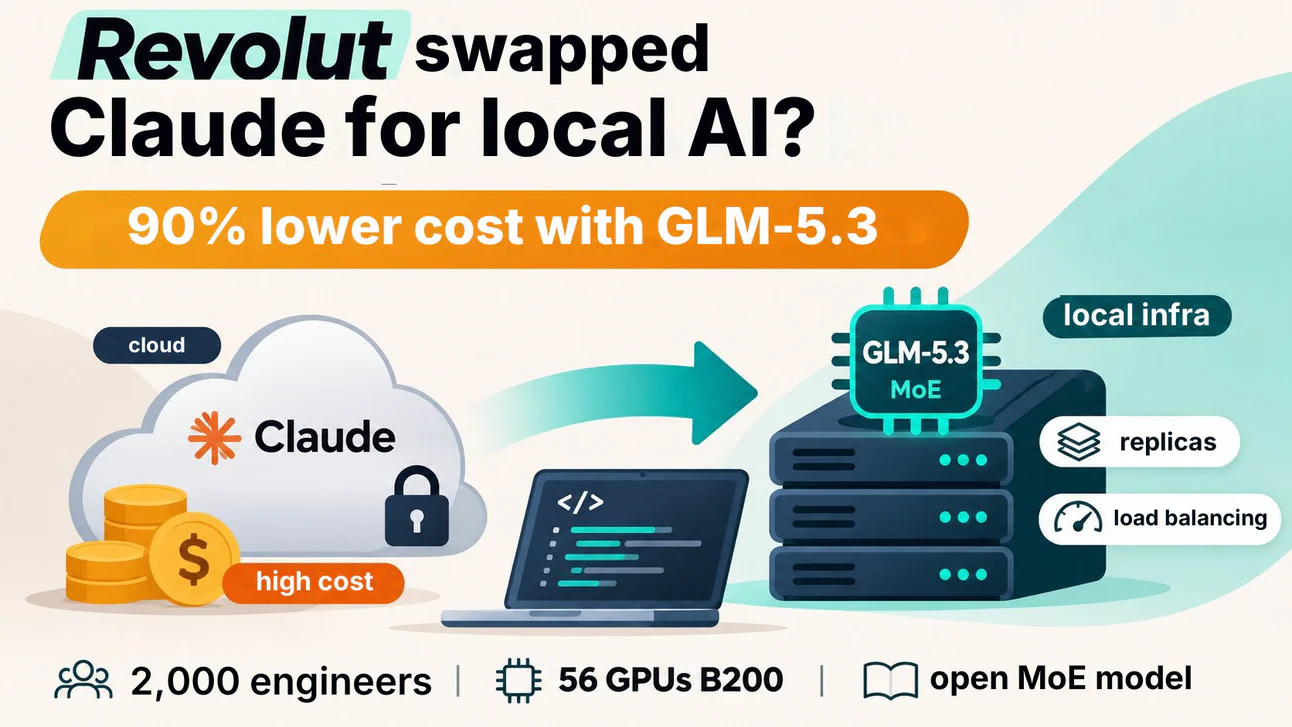
Last week some VERY relevant news came out for big companies. @Revolut, the UK digital bank, said it swapped Claude for a Chinese model running locally and, with that, is saving 90% of the costs.
David Abitbol, the company’s infra lead, said there were engineers spending between 1,000 and 10,000 dollars a month on AI coding tools, with no ROI to justify it. And that this switch would be very much worth it.
My first reaction was: I doubt it. So I went to check their claims: that it was running for 2000 engineers, at a speed of 200 tokens/second, on 8 NVIDIA DGX B200 machines (56 B200 GPUs in total). My second reaction: I DOUBT it runs at that speed on that cluster.
But after studying it a bit more deeply, I could see that it really is possible, with a few asterisks.
The model they’re running locally is GLM-5.3, which has 753B parameters (that’s a lot) and is really excellent for code. The key insight is that, like almost all of today’s top models, it’s a MoE (Mixture-of-Experts). That means even though the whole neural network (all 753B parameters) has to be loaded in memory, to generate responses it activates only 40B. I also believe they’re using a quantized version of the model, which also optimizes speed and loses almost nothing in quality (I have an article about quantization on my blog, which I’ll leave in the first comment below).
Another smart move on their part was not spinning up just one GLM-5.3, but several replicas of it, and doing well-built load balancing. That way, an engineer doesn’t have to sit waiting for that single model to finish someone else’s response.
And what closes the story is that they didn’t swap EVERYTHING for this in-house solution. They said that, for complex problems, engineers still have access to Claude Code and Codex, but that GLM-5.3 becomes the jack-of-all-trades for everyday programming tasks. And honestly, any model of this caliber (GLM, Kimi, DeepSeek, Muse) is already good enough to do CRUD and those things that are 90% of what a dev does every week.
As results, they reported a 60% improvement in coding time and 70% in lead time (worth the honest note that these numbers are self-reported, and part of the gain may come simply from removing the usage limits of the private models, not from the model itself).
One last big asterisk is in order here: each of the DGX B200 machines they used (and they have 8) costs between 600 and 900 thousand dollars. In other words, a small or medium company won’t be able to replicate this at that scale or speed. This math only works out for those who already have the volume (and the cash) for it.
Either way, it’s an important sign that open models like GLM-5.3 have already reached a level competitive enough to justify this kind of bet in production, at a giant fintech processing sensitive code every day.