New Chinese model: Qwen3-Max
Published on
One of the MAAANY launches from China’s Alibaba Group Qwen this past week (let them cook!) was Qwen3-Max.
For those who haven’t been following, the Qwen team is on a strong streak of releases (almost 10 in this last week alone), and this is their flagship model. They launched the Qwen3-Max-Instruct version, a model with over 1 trillion parameters trained on 36 trillion tokens (to give you an idea, it’s speculated that the top models are trained on ~15-20 trillion tokens).
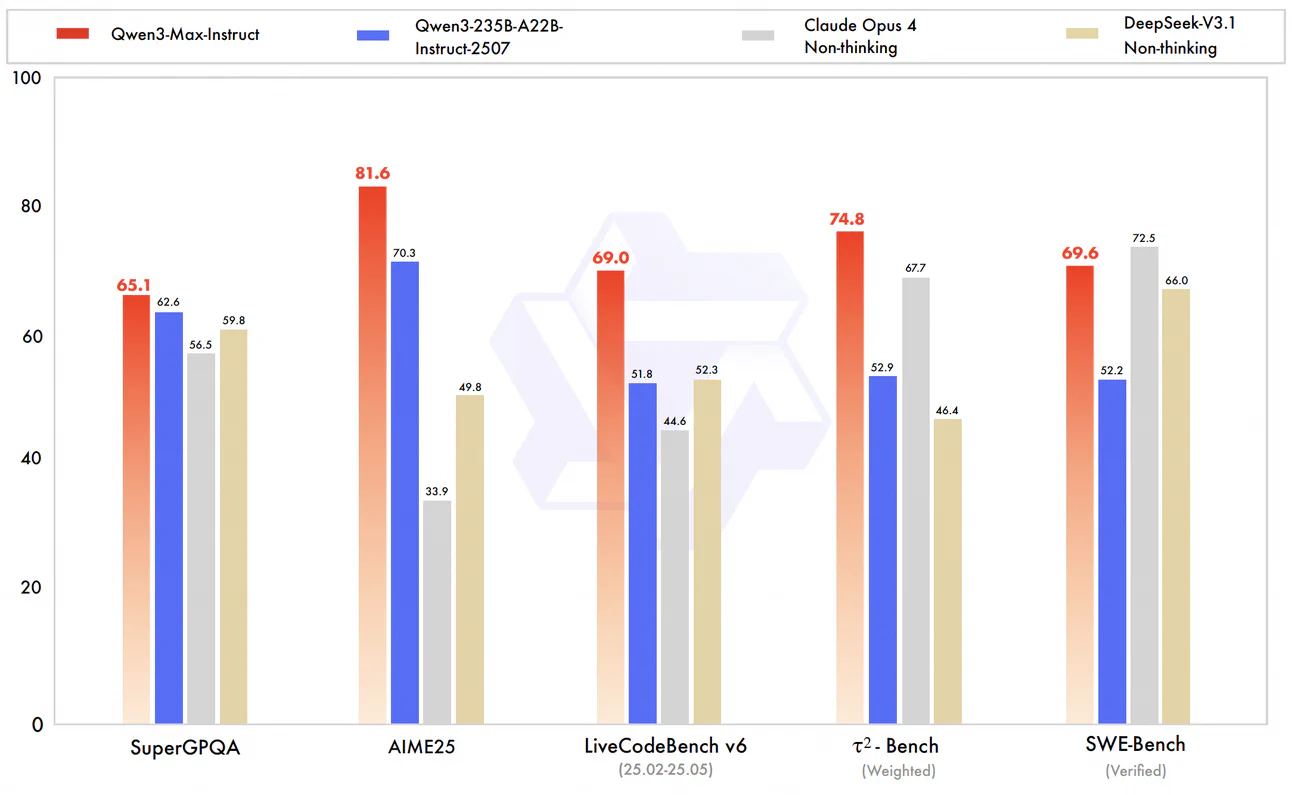
And the results are excellent, especially in programming and agent use. On a benchmark that focuses on solving real-world coding problems (SWE-Bench), it scored 69.6%, placing itself among the best in the world. On the agent side (tool-calling), it beat models like Claude Opus 4 and DeepSeek V3.1. Not bad!
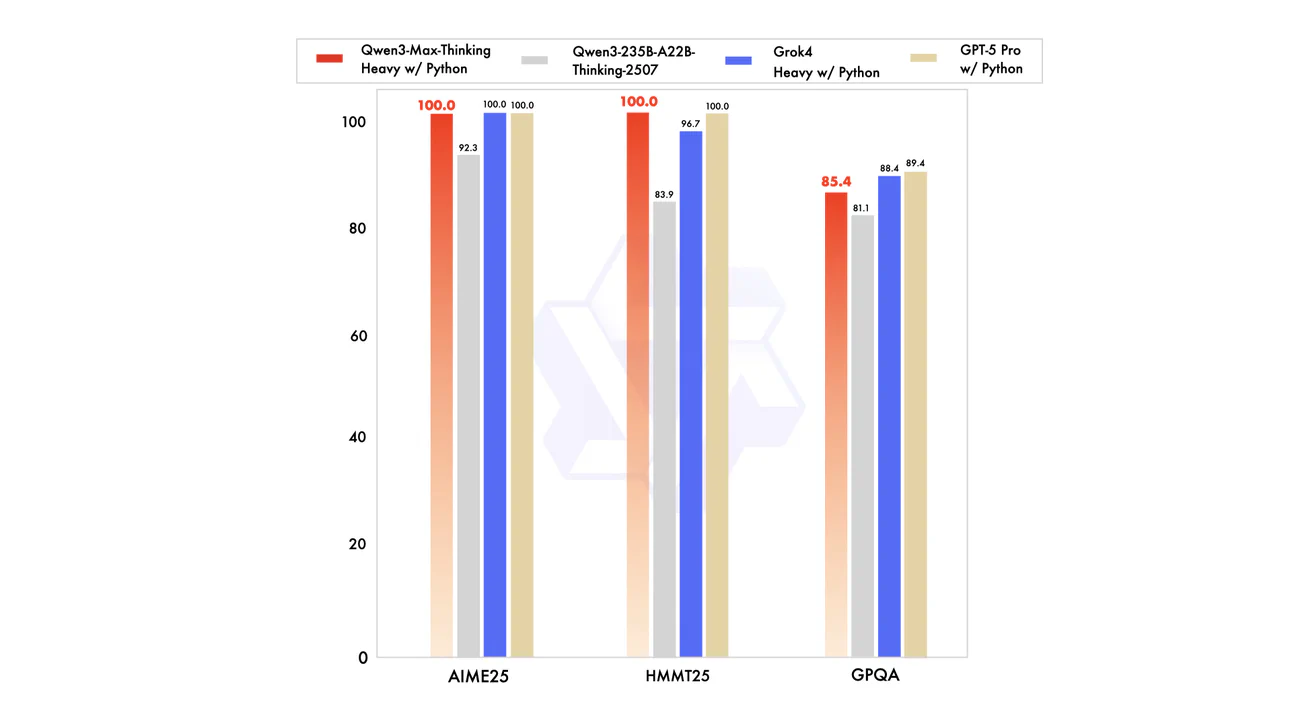
The second one, which is still in training, is Qwen3-Max-Thinking, which seems absurd. Using a code interpreter and more compute time, this version has already hit 100% on math reasoning benchmarks, like AIME 25 and HMMT. Yes, 100%. We’ll have to wait and see what else it can do when it’s officially released.
For those who enjoy the technical details, I found it interesting that, according to them, the training was super stable, without the famous “loss spikes” that usually cause headaches in models this big, thanks to the MoE (Mixture of Experts) architecture.
And the best part for developers: it can already be tested on Qwen Chat or via API on Alibaba’s cloud, and the API is compatible with the OpenAI standard, which makes integrating it a LOT easier.
One more heavyweight contender in the fight for the top! The competition just keeps heating up.